The model upgrade test: run one role on two models and compare cost per completed job
Release notes 2026-09-15 — vocion-core#323 (merged) adds a model override to evals and a comparison that reports pass rate, tokens and cost per passed case; GPT-6 Astra, the GPT-5.6 family and the Claude 5 family are priced in the catalog.
Shipped: vocion-core#323, merged to main on 2026-09-15 as 297f420a. Part of the 2026-09-15 release notes.
The outcome
When a frontier model ships, the roles you already run should get better without being rebuilt. That is a claim you can test rather than believe: take one agent, run its eval dataset on the model it uses today and on the new one, and read three numbers — did more cases pass, did it take fewer turns, and what did each passed case cost. Price per token is not the metric; cost per completed job is.
What it is
A model override for evals. EvalService.runDataset({ modelOverride, providerOverride }) runs an agent's dataset with a different model while the judge stays on the classifier model. The run is stamped with the model (eval_run.model) and every case records tokens in and out, cents, and model turns (eval_case_result.usage). Metrics gain passed, totalCents, meanTurns and costPerPassedCaseCents. Migration 0093 adds two nullable columns.
The comparison. packages/core/src/services/evals/modelUpgradeTest.ts runs baseline then candidate — sequentially, on purpose, so shared tools and the budget row are not contended — and compares them: pass rate, mean judge score, total and per-case cents, tokens, mean turns, cost per passed case, and the per-case side-by-side with the judge's one-line rationale. It publishes the result as a Briefing to the agent's team. The report leads with the outcome sentence; the token tables are evidence underneath.
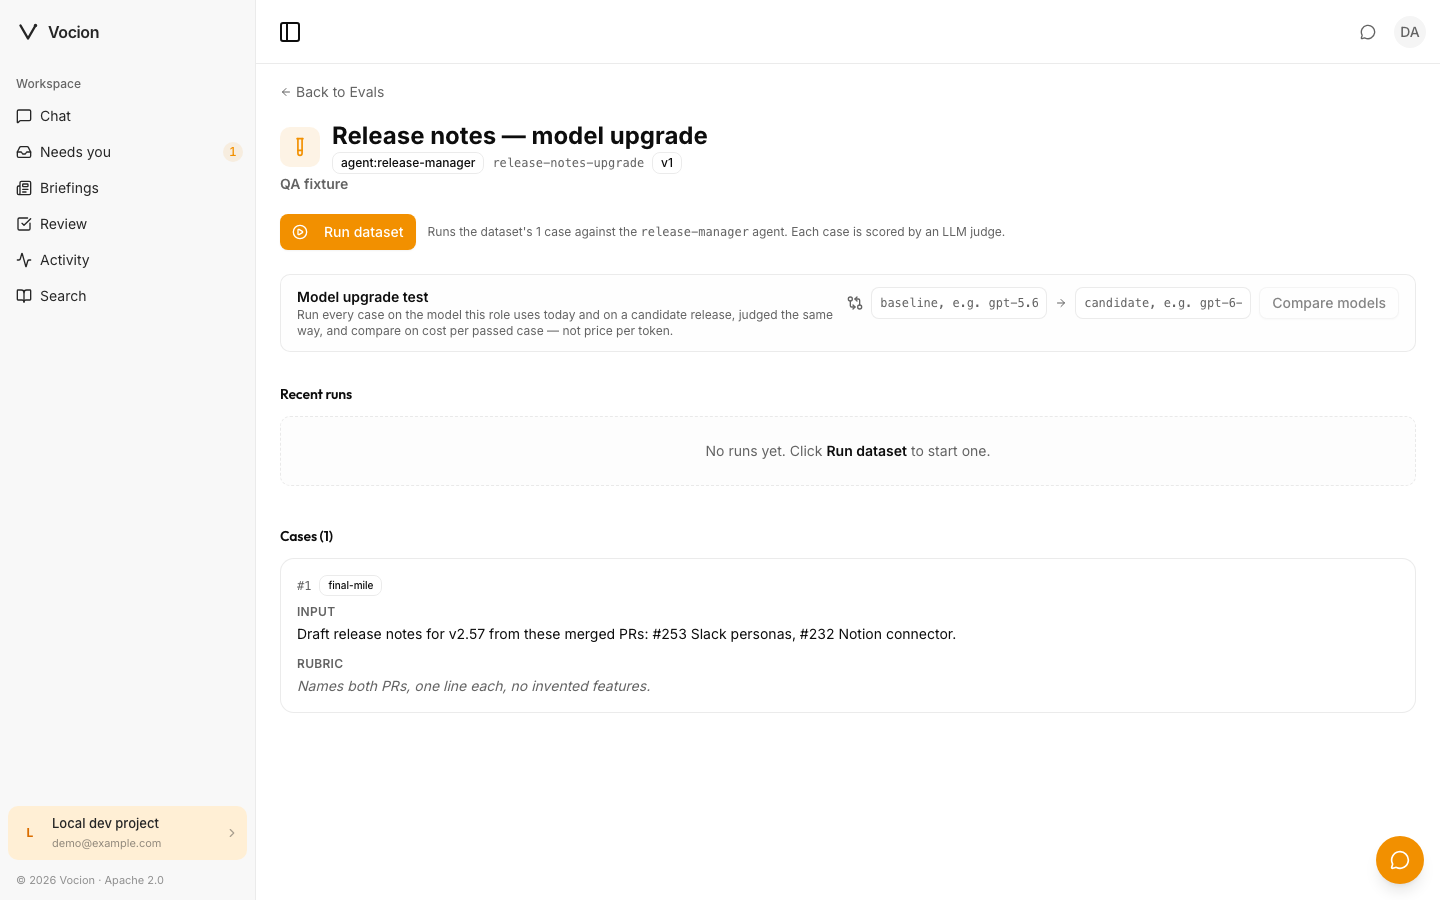
Surfaces. POST /api/v1/evals/:slug/model-upgrade-test { baselineModel, candidateModel }; a Compare models form on /dashboard/evals/[slug] and a compare page for two finished runs; npm run eval:upgrade -- --dataset <slug> --baseline <m> --candidate <m>, which exits non-zero if the candidate's pass rate is lower.
Pricing. packages/core/src/libs/pricing.ts gains GPT-6 Astra and the GPT-5.6 family at the list prices on OpenAI's pricing page, and the Claude 5 family (Fable 5.1, Opus 5, Sonnet 5, plus the undated Haiku 4.5 id) at Anthropic's list prices. Rows are additive. One id is deliberately left unpriced — the scaffold default gpt-5.4-mini — because it is not on the published page; the PR asks rather than guesses.
Writing a dataset that tests the right thing
The dataset entity (docs/entities/eval-dataset.md) has not changed. What matters for an upgrade test is that inputs are self-contained — paste the context in, so the test does not depend on a connector being synced — and that rubrics name the final mile: follows the stated template, leaves nothing marked "TBD" where the input had the fact, marks pricing as a draft range, cites the proof it was given, invents nothing. Tag cases by the kind of work so the gained and lost cases slice by kind.
Caveats
Tenants running the newly priced ids start accruing real cents in agent_budget where they accrued zero; a hard limit that never bound may start to. The provider is inferred from the model id for the override path only; defaults do not change.
Guide: [docs/guides/model-upgrade-test.md](https://github.com/vocion/vocion-core/blob/main/docs/guides/model-upgrade-test.md).
Where this lives in the repo
- Pricing rows:
packages/core/src/libs/pricing.ts(+pricing.openai.test.ts) - Provider inference for the override path:
packages/core/src/libs/llm/langchain.ts(inferProviderForModel); the override itself inservices/agents/harness.ts(ModelOverride,getCompiledAgent(org, slug, { modelOverride })) andservices/AgentService.ts(runAgentDeepgainsmodelOverrideand returnsusage) - Evals:
services/EvalService.ts(runDataset({ modelOverride, providerOverride })), migrationpackages/core/migrations/0093_eval_run_model.sql - The comparison:
services/evals/modelUpgradeTest.ts(runModelUpgradeTest,compareEvalRuns,renderComparisonMarkdown) - Route and pages:
app/api/v1/evals/[slug]/model-upgrade-test/route.ts,app/[locale]/(auth)/dashboard/evals/[slug]/page.tsx,…/compare/page.tsx; scriptnpm run eval:upgrade - Guide:
docs/guides/model-upgrade-test.md